
Mixture of experts (MoE) is a way to build an AI model from many smaller sub-networks, called experts. For each token, a router picks a few experts to do the work. The rest stay idle.
This lets a model hold a huge number of parameters but use only a small share of them per token. You get much of the quality of a big model at the speed and cost of a smaller one.
How mixture of experts works
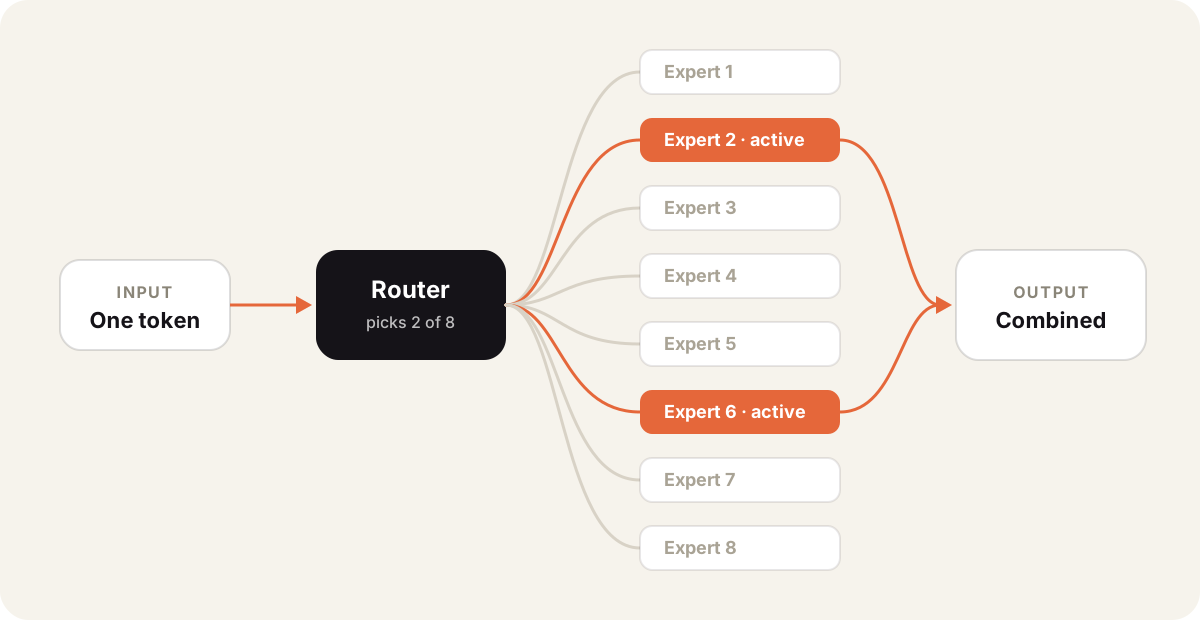
- A token arrives. A token is a word or part of a word.
- The router scores the experts. It is a small network trained to pick the best experts for each token.
- Only the top experts run. Their outputs are weighted and combined.
- The next token may use different experts. Routing happens again for every token and every MoE layer.
The experts don’t map neatly to subjects like “math” or “French”. They specialize in patterns the model finds useful during training.
Real examples
| Model | Total parameters | Active per token | Source |
|---|---|---|---|
| Mixtral 8x7B | 46.7B | 12.9B | Mistral AI |
| DeepSeek-V3 | 671B | 37B | DeepSeek-V3 report |
Mixtral uses 2 of its 8 experts per token, as described in its paper. DeepSeek-V3 runs about 5.5% of its parameters for each token.
Why it matters to you
- Lower cost, less compute per token means cheaper answers. That is part of why some MoE models cost so little to use.
- Faster replies, fewer active parameters means quicker generation.
- Big memory needs, all experts must still be loaded. A 671B MoE model needs far more memory than a 37B dense model, which makes it hard to run as a local LLM.
You can try DeepSeek models in Sparkian and compare them with dense models like Claude Haiku in the same chat.